Fine-tuning GPT-2 XL on a free GPU
My first fine-tune: teaching a 1.5B-parameter model from 2019 to suggest five synonyms or antonyms for any word.
- When
- Summer 2025
- Role
- Research intern, ASU AI Acceleration Lab
- Outcome
- From garbled text to 3–4 sensible words out of 5
- Built with
- GPT-2 XL, Hugging Face Transformers, Google Colab T4
Why I started
I needed to learn fine-tuning, and I wanted to do it on something real instead of following a tutorial. So I made up my own use case: complex enough that prompting alone couldn't solve it, and simple enough to finish.
What I did
I started on AWS SageMaker, but it expects training data in S3 and my dataset lived on Hugging Face, so I switched to Colab's free NVIDIA T4.
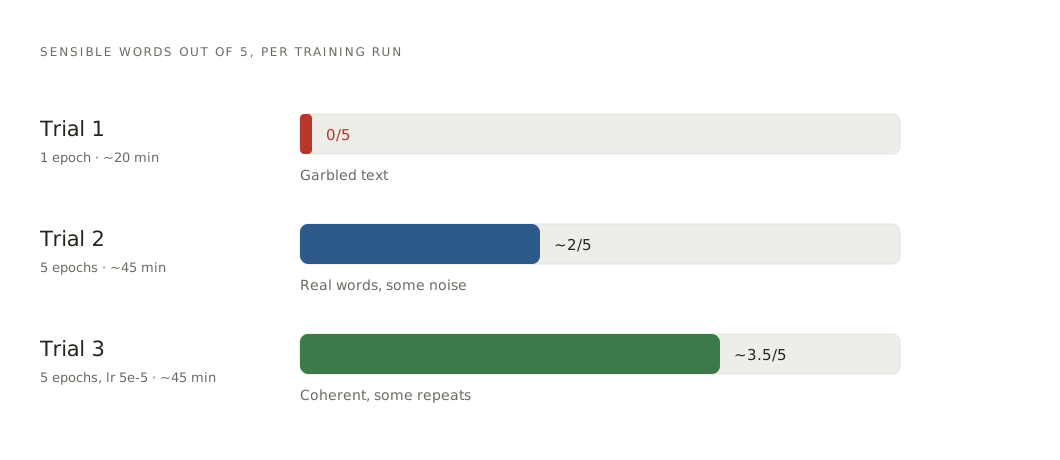
My first overnight run (about 12 hours) died at Colab's session limit, so I learned to work within it. Across three runs I tuned epochs, batch size, and learning rate.
Progress so far
Trial 1 produced garbled text. By Trial 3, the model reliably gave five words in a clean format, and 3–4 of them made sense. The biggest jump came from going from 1 to 5 epochs.
What's next
Next time: Mistral 7B or Llama 3 8B with Unsloth QLoRA. 1.5B is too small for good output.